BLOG
AI Training Data Collection in India: Field, Multilingual & Verified Datasets at Scale
 About Anaxee
Every AI team eventually hits the same wall. The model performs beautifully in the lab and then stumbles the moment it meets the real world, a Bhojpuri voice command, a handwritten Marathi shop board, a crop disease photographed on a cheap phone in a Chhattisgarh field. The architecture was never the problem. The training data was.
The data that teaches a model to work in Bharat has to be collected in Bharat, from real people, in real conditions, with their consent. That is a last-mile, feet-on-the-ground problem long before it is a machine-learning one, and it is exactly the kind of problem Anaxee was built to solve.
What AI training data collection actually involves
Useful training data is not scraped, it is produced. A real pipeline runs in stages, and most AI teams underestimate how much of the effort sits in the first two.
Annotate / label
Verify & clean
Ready-to-train dataset
Collection is the hard, physical part: finding the right people, capturing clean samples across languages and regions, and proving each one is real and consented. Annotation and verification then turn raw captures into a dataset a model can actually learn from.
Why collecting AI data in India is hard
Need real-world, multilingual, consented data from across India? Anaxee collects image, audio, video and text data at the source, with geo-tag, timestamp and AI quality checks on every sample.
What good AI data collection looks like
Multimodal by default
Speech, images, short video, handwriting, typed and dictated text, captured to spec with the right metadata. The value is in collecting the modality your model is weak at, not the one that is easy to find.
Multilingual and truly local
Real coverage of India means dozens of languages and dialects, captured by local people who actually speak them, across the kind of towns and villages where the next wave of users lives. This is the same deep reach we use for field data collection across India.
Consent-first and verifiable
Every contributor gives recorded consent; every sample carries a geo-tag, timestamp and a traceable chain back to the field. That is what turns a pile of files into a dataset you can defend.
Where technology and AI change the game
Anaxee runs collection through one app, so quality is enforced as the data comes in, not weeks later. Each sample is geo-tagged and timestamped; AI checks images and audio for blur, silence, duplication and location mismatch on the spot; and a central dashboard shows coverage by language, district and modality in real time. You see where the gaps are and fill them deliberately, instead of discovering a biased dataset after training. It is the same quality layer that powers our view on why real-world primary data still beats synthetic data.
How Anaxee helps AI teams
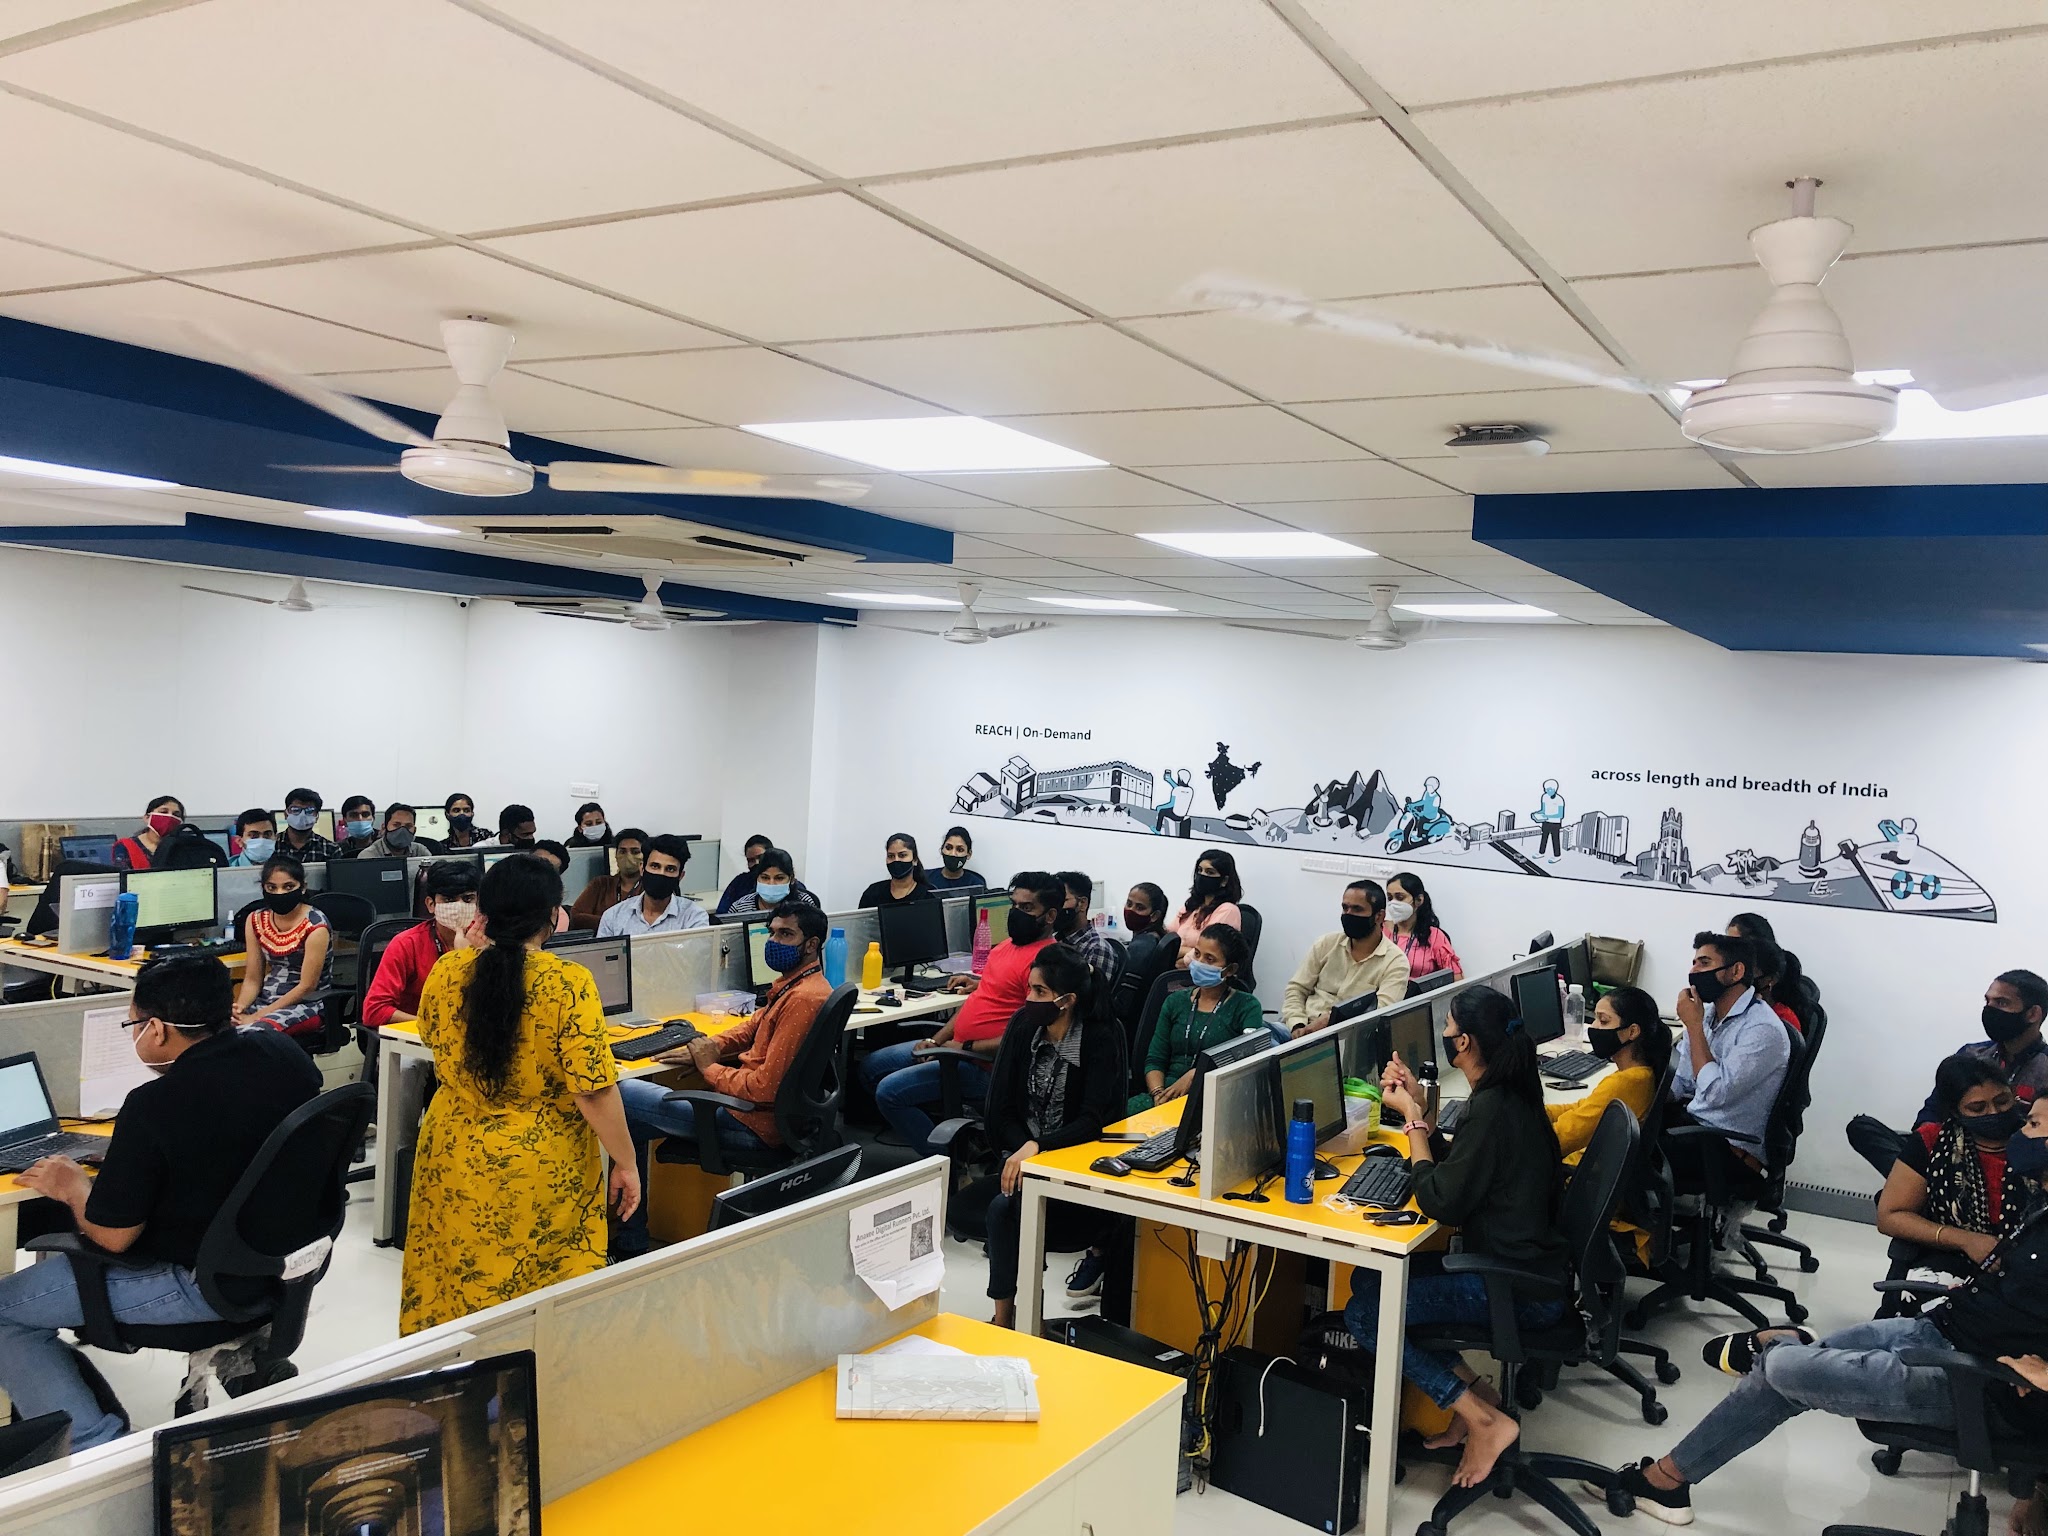
Anaxee is India’s Reach Engine: 40,000+ tech-enabled Digital Runners across 540 districts, 26 states and 11,000+ pincodes, with a field app that has crossed 100,000+ downloads and 3M+ completed person-projects. For AI and data teams, that network becomes a programmable data-collection layer, you specify the languages, modalities, scenarios and volumes; we collect at the source, with consent and verification, and hand back clean, structured data. It connects to your pipeline through our platform and API, and scales from a focused pilot to a nationwide collection drive.
Independent field data at national scale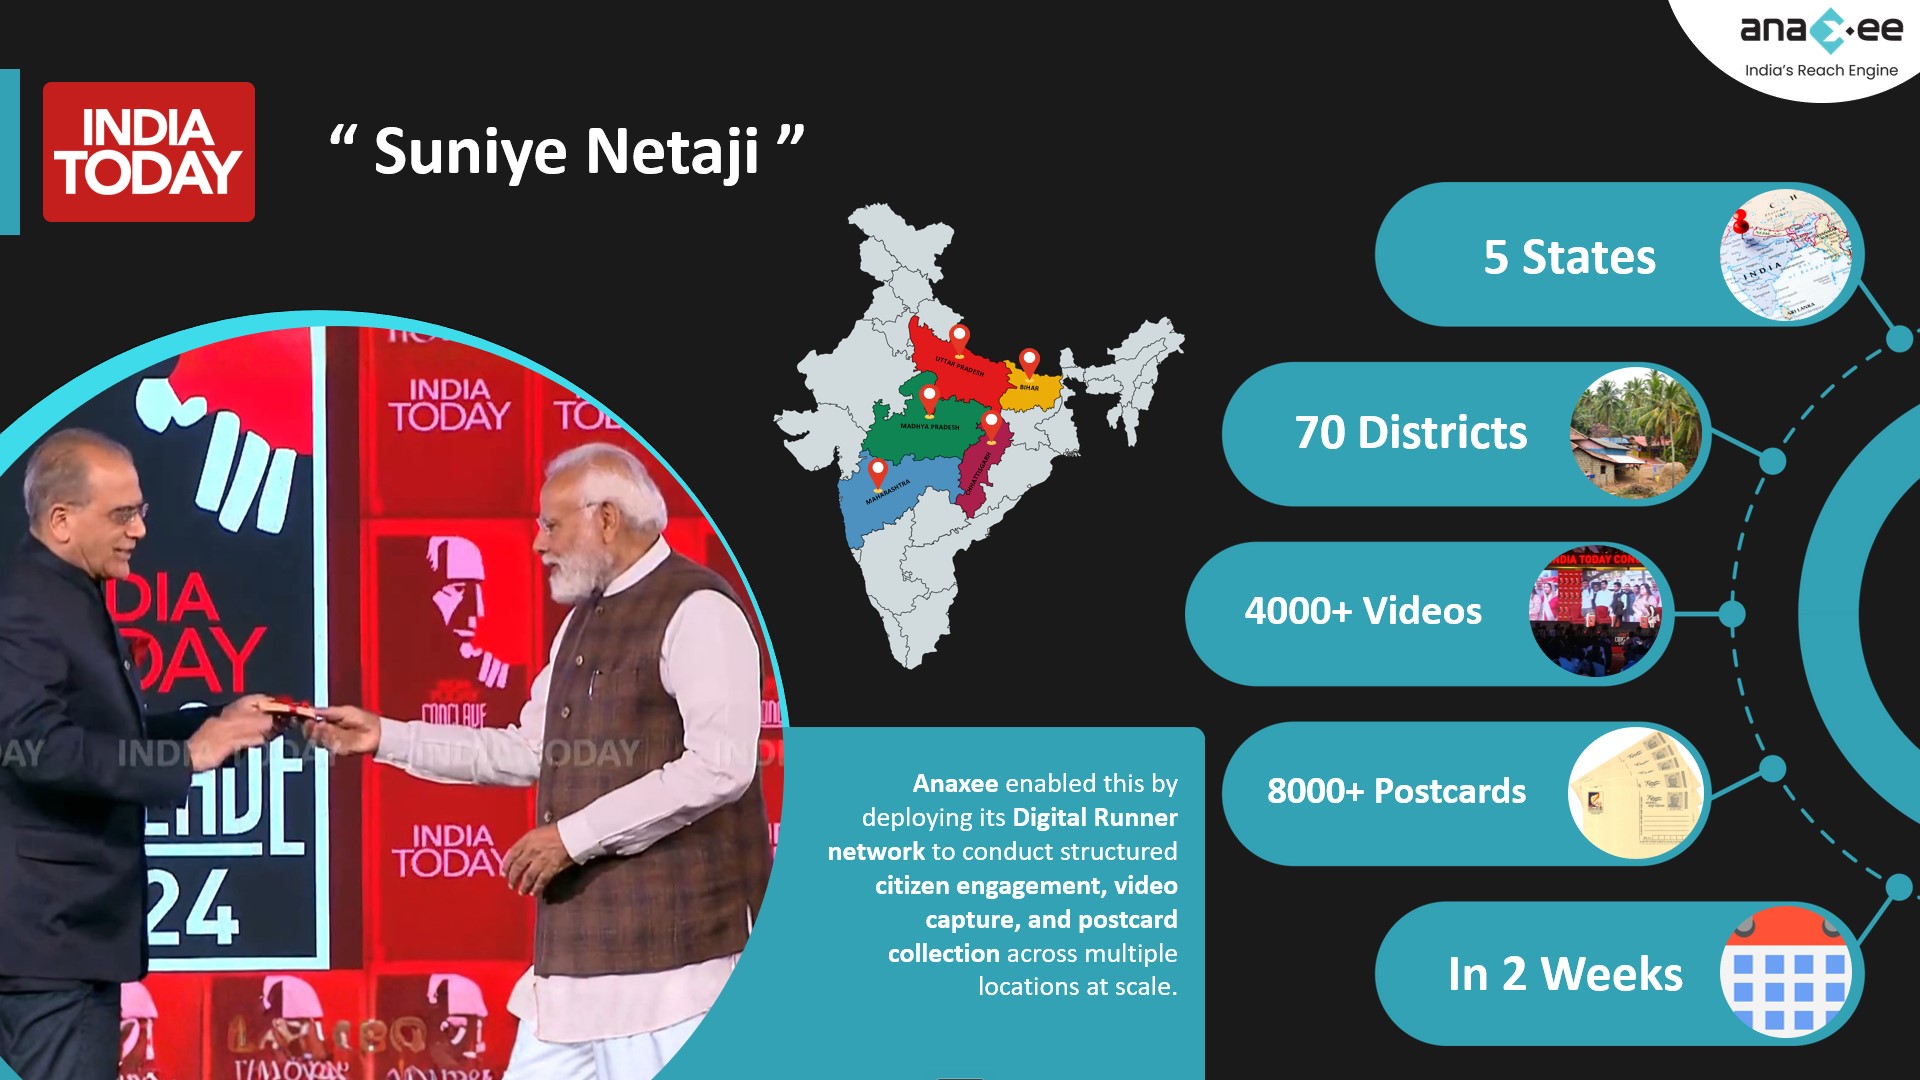
What happens when you reach out to Anaxee
- We scope your data need, modalities, languages, scenarios, volume, consent terms and acceptance criteria.
- We run a pilot in a few districts so you see real, verified samples and quality before committing to scale.
- We scale collection across 540 districts, with live coverage-by-language dashboards and QA on every sample.
Frequently asked questions
What is AI training data collection?
What kinds of data can Anaxee collect?
How do you ensure data quality and diversity?
Is the data consented and compliant?
Do you only collect, or also annotate?
How quickly can a collection project start?
The bottom line
As the easy, scraped data runs out, the advantage shifts to whoever can commission fresh, diverse, consented data from the real world, on demand. In India that is a last-mile collection problem at heart. Anaxee turns a network of 40,000+ Digital Runners into the data-collection layer that feeds your models the Bharat they need to understand.
Ready to collect the data your model is missing? Let us scope a pilot in your target languages and modalities.